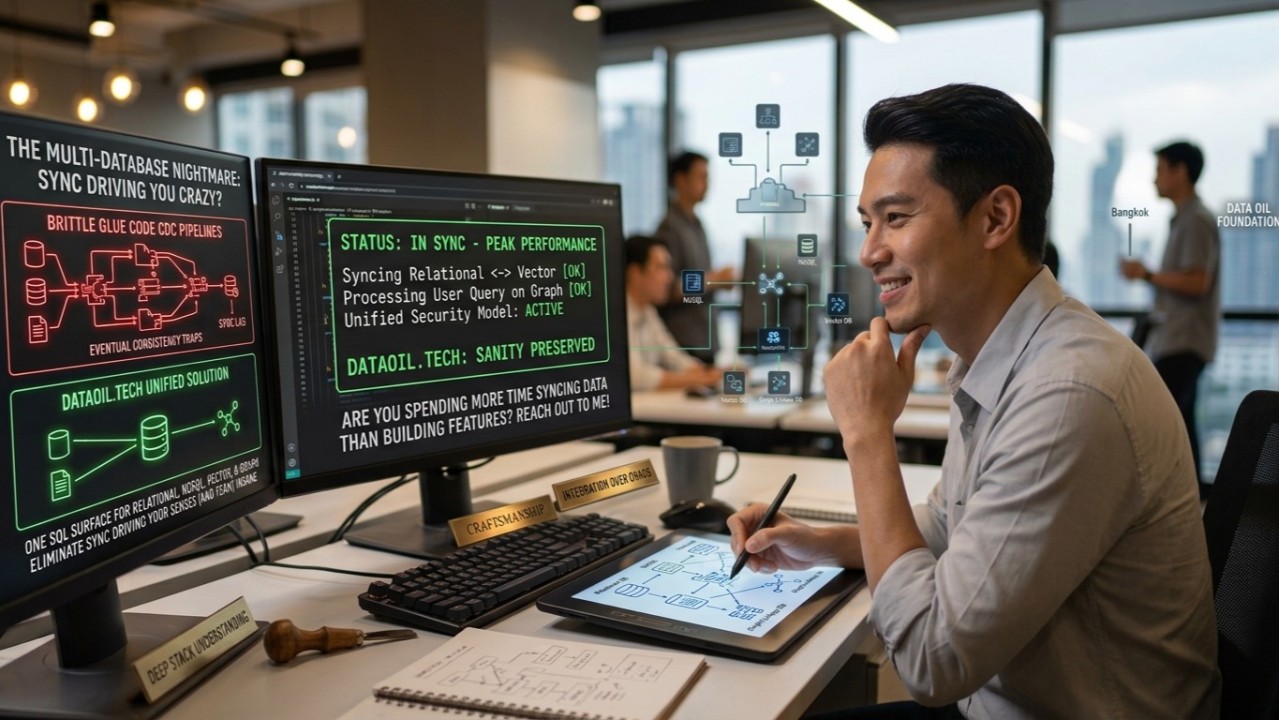
If your modern tech stack looks like a patchwork quilt of specialised databases, you are not alone.
To build a modern application, you usually need:
- A Relational DB (PostgreSQL/MySQL) for transactional truth and ACID compliance.
- A NoSQL/Document DB (MongoDB) for flexible, unstructured schema needs.
- A Vector Store (Pinecone/Milvus/Qdrant) for semantic search and AI embeddings.
- A Graph/Linkage DB (Neo4j) to map complex relationships and lineage.
- A Search Engine (Elasticsearch) for fast full-text search.
On paper, this “best-of-breed” architecture sounds perfect. Every workload gets its ideal tool.
In reality? It’s an operational nightmare.
Moving from Data Chaos to Single-Surface Efficiency: How DataOil Changes the Game
Instead of stitching together five separate database platforms with brittle glue code and ETL pipelines, modern engineering teams are turning to DataOil.
DataOil (dataoil.tech) offers one SQL surface over everything a modern application stores: rows, unstructured documents, graph/linkage relationships, full-text search, and AI vectors, all accessible in one place.
Here’s how DataOil restores balance (and sanity) to your stack:
- Eliminates Sync Lag: By bringing relational data, document collections, graph links, and vector embeddings under one unified engine surface, you no longer need external sync scripts or fragile CDC streams to keep your models aligned.
- Peak Performance Without Sacrificing Reliability: Query across relational structures and AI vectors natively without round-tripping across distinct cloud network hops.
- Unified Security & Governance: Define access controls and residency rules once, rather than trying to match permissions across five separate database vendors.
- Sanity Preserved: Your developers write queries against a unified SQL interface instead of learning five different query DSLs and debugging race conditions at 2 AM.